TLDR We trained a series of 7B LLMs named XGen-7B with standard dense attention on up to 8K sequence length for up to 1.5T tokens. We also fine tune the models on public-domain…
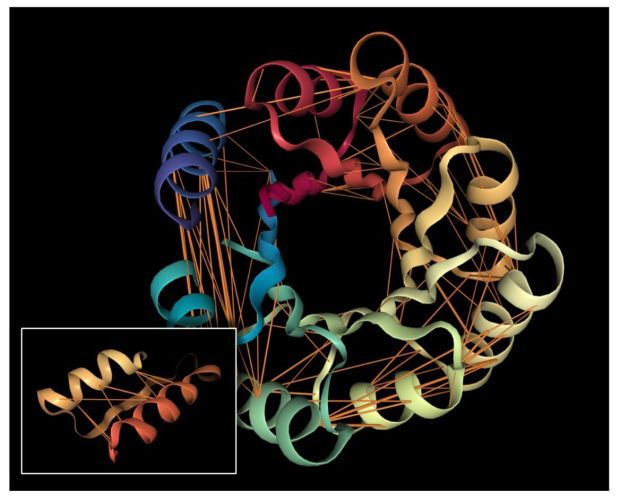
In our study, we show how a language model, trained simply to predict a masked (hidden) amino acid in a protein sequence, recovers high-level structural and functional properties of proteins.