
Post-training methods (RLVR, On-policy distillation) are Episode-local Language models are getting better at learning from feedback during post-training. In reinforcement learning with verifiable rewards (RLVR), a model tries a problem, a verifier checks…
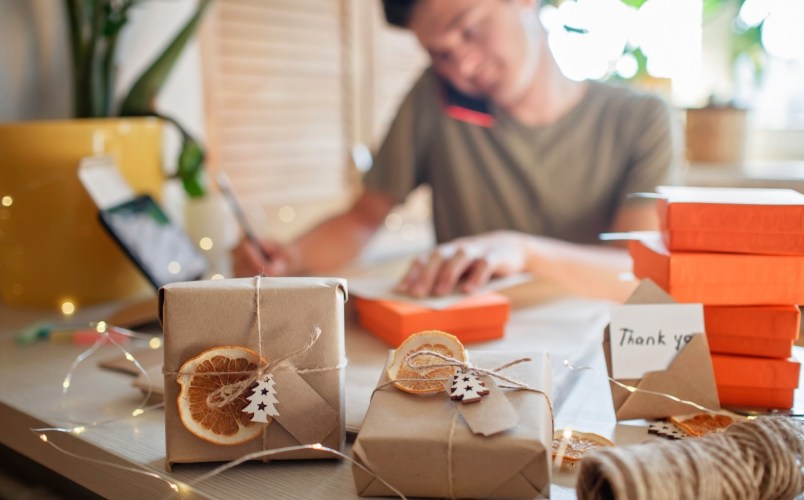
Holidays dedicated to small businesses can boost revenue and build lasting customer loyalty throughout the year.


Kacie Molina had no formal education and almost no tech exposure. Through Talent Stacker, Trailhead, and the Trailblazer Community, she transformed curiosity into a Salesforce career and discovered opportunities she once thought were impossible.
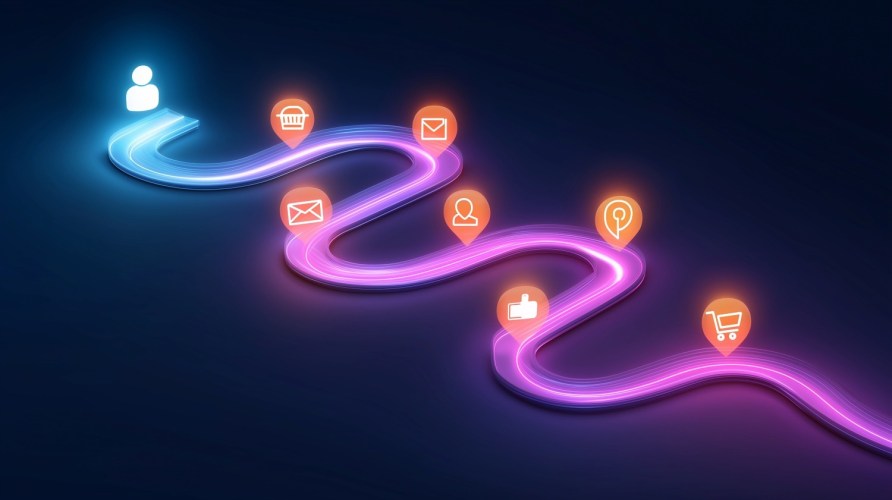
Learn how to map every interaction to build stronger relationships and grow your small business faster.
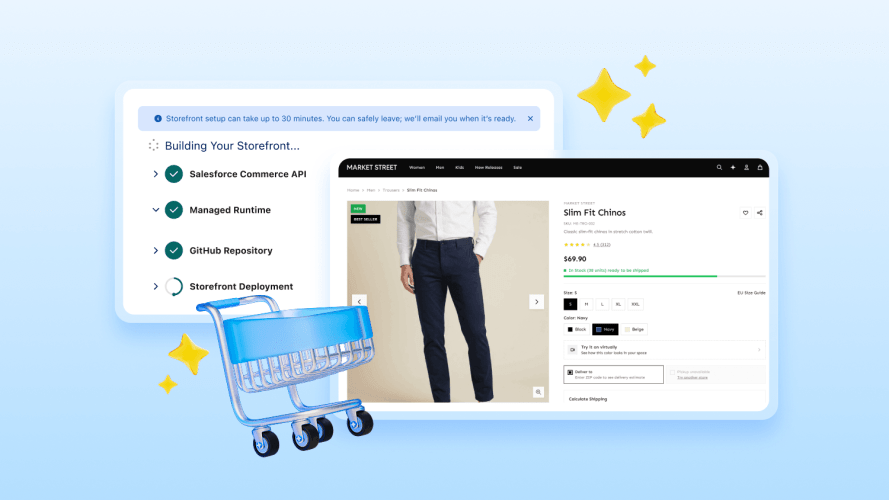
As businesses rush to adopt agentic commerce, development teams are typically up against one of two predicaments. Some struggle with commerce platforms they have outgrown. What was once an ‘easy’, lightweight solution has…


You’re ready to lead your team to greatness. Here are a few inspirational ideas to get started.

These BigCommerce alternatives can help your small business sell more, fast.
No, email is not perfect, but many of its challenges are solvable if you go about it the right way. Here's how.

Make better financial decisions with this curated list of blogs tailored specifically for your growing business.