Using our "Customer Zero" philosophy, we were able to automate data security and find hidden PII at a massive scale.

Post-training methods (RLVR, On-policy distillation) are Episode-local Language models are getting better at learning from feedback during post-training. In reinforcement learning with verifiable rewards (RLVR), a model tries a problem, a verifier checks…
Learn how to use Salesforce Data 360 to build a governed semantic foundation that humans and agents can both rely on.
Holidays dedicated to small businesses can boost revenue and build lasting customer loyalty throughout the year.


Kacie Molina had no formal education and almost no tech exposure. Through Talent Stacker, Trailhead, and the Trailblazer Community, she transformed curiosity into a Salesforce career and discovered opportunities she once thought were impossible.


A Note from our General Manager Welcome to the first edition of the Life Sciences Cloud newsletter. I’m thrilled to launch this new forum for sharing customer stories, industry innovation, and the latest…


Explore recurring architectural anti-patterns through real-world scenarios and practical approaches for designing more resilient Salesforce architectures.
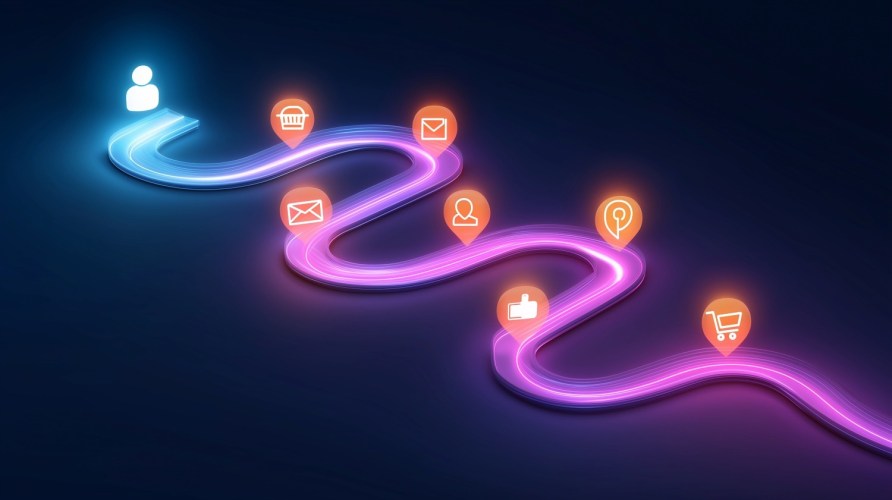
Learn how to map every interaction to build stronger relationships and grow your small business faster.


Start by evaluating fit, then build an economic model that is profitable for both you and partners.